Introduction
It’s been almost two months since my last post about the Dynamic Model Router, where I wrote about configuring and optimizing GLM 5.2 through Mistral’s API. Since then, a lot has happened: roughly 148 commits, 21 new architecture decision records, and a new release, v1.6.1. The test suite grew to 1140 passing tests along the way. This post is a guided tour of what landed, not a changelog you could have read on GitHub. Although, spoiler: there is a changelog, and it is thorough.
If you’re new to the series: the router is a Pi extension that classifies every prompt and routes it to the group of models that fits it best, balancing intelligence, cost, and availability. The Smart Model Routing post covers the idea, and the last post covers the configuration.
What drove this release wasn’t a feature wishlist. It was two things: real money leaking through a $0-cost tie-breaker, and an engineering article from Spotify that made me question where tokens actually burn. Both taught the router a few lessons, and most of what follows is what it learned.
The Spotify Article That Started It: Cheaper Models Inside an Expensive Session
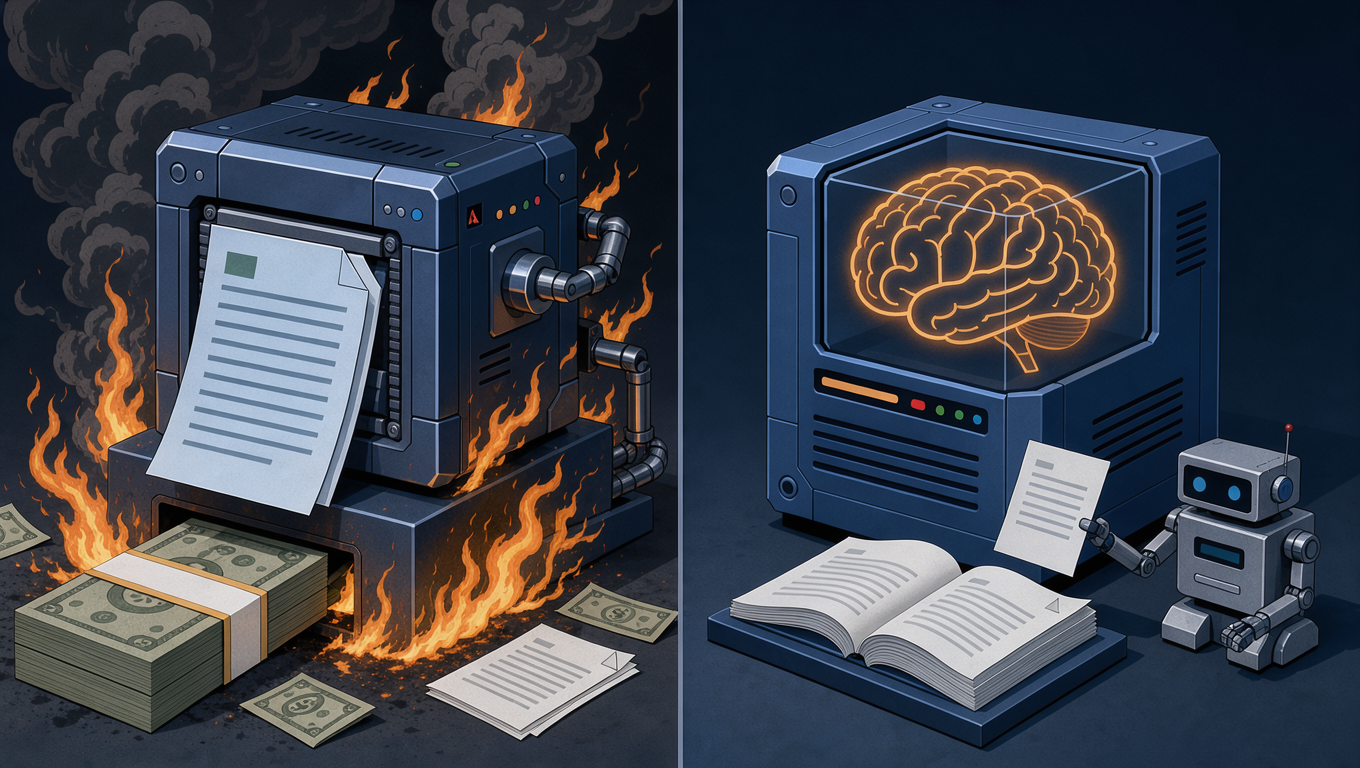
In early September, Spotify Engineering published a post titled „Portal by Spotify cut my Claude Code token usage by 90%“. Its core observation hit home immediately: most of what an AI coding agent does isn’t thinking. It’s I/O. Reading five files to answer a question about one method. Generating a test file that follows the exact same pattern as the twenty test files next to it. Thousands of tokens burned with almost zero reasoning, all of it fed to a frontier model that is wildly overqualified for the job.
Their answer was to delegate the grunt work: two lightweight „modes“, bulk-reader and code-writer, running on a cheap worker model (Gemini 2.5 Flash in their examples), callable from Claude Code through a plugin called shunt. Hooks block oversized file reads before they happen. The cheap worker digests the files and returns a concise answer, so the corpus never enters the expensive model’s context at all. Generated code goes straight to disk; the expensive model never even sees it. Their benchmark on a Java monorepo: mean savings of roughly 90% on bulk reads.
I don’t run Claude Code as my daily harness. I run Pi with my Dynamic Model Router. Now, routing prompts to cheaper models is what the router has always done, in every previous version. What it couldn’t do until now was intervene in the workflow itself: a file read gets blocked before it happens, the reading is delegated to a cheap model, and the expensive model continues with the result instead of the raw files. That’s the real step change of v1.6.0, and it answers the same question the Spotify post raises: why should the expensive model read the files at all? So instead of bolting on a separate plugin, I built the equivalent into the router itself: two new groups, bulk_reader and code_writer, with delegation enforced by the router rather than suggested by a prompt.
In v1.6.0, that looks like this:
- Both groups carry a
min_context_lengthfilter (resolved registry-first vialookupContextWindow()), so a bulk-read task never lands on a model that silently truncates the corpus. - The router shrinks read results before they reach a delegation-capable model, and that includes bash tool output, not just file reads.
- Oversized full-file reads are blocked up front and answered via
bulk_reador the delegation group instead of being streamed into context. - And the first line of defense for expensive models: anything in
delegation.expensive_groups(strategic and tactical, by default) gets every full-file read blocked and redirected toward targeted reads. A stale-turn guard and fail-open semantics make sure the guard itself can never wedge a session.
The article is refreshingly honest about what doesn’t delegate: editing (summaries don’t carry reliable line numbers) and reasoning (the cheap worker missed a subtle thread-safety bug that the frontier model caught in seconds). That matches my routing boundaries: debugging and architectural decisions stay on the strong groups. Where Spotify pays a 10–30 second network round-trip per delegation, though, the router has an advantage: the delegation target is just another routed group. The grunt work can go to a local Ollama model or whatever cheap cloud candidate the router currently trusts, with no platform subscription required.
That was the real motivation: dynamic routing, taken from the prompt level down into the workflow itself, and far fewer tokens burned along the way. The expensive model gets to think. The cheap models get to read, summarize, and scaffold.
Cloud-First Routing and Billing Preferences
The second driver was the money. The router’s job is to pick the cheapest capable model for a task. But „cheapest“ turned out to be harder to determine than I thought.
The trigger was a live finding from late September: when the router resolved cost ties at $0, it fell back to GDPval scores, and that tie-breaker started burning through my Claude subscription quota for throwaway prompts. Subscription models are free to me at the margin, but not actually free: subscription time is a budget, and the router was spending it on prompts that any free model could have handled.
v1.6.0 introduces a billing_preference mode per group:
cloud_first: prefer cloud models, and only fall back to local Ollama if the cloud is down.local_before_payg: keep free and subscription models ahead, and let local Ollama models run before anything pay-as-you-go. You only pay when even your local hardware can’t serve the task.
Alongside that, the cost resolution itself got an overhaul. It is now strictly registry-first: Registry → local → subscription → cache → :free → unknown. Subscription models get real prices attributed to them instead of being dumped into max_cost: 0 groups, unknown costs no longer flip cheap groups to „strongest model first“, and the live „is free“ check no longer trusts a stale scan cache that claims $0. As a result, Ollama is now a fallback in my setup rather than the default, and five of my groups got reordered around that insight.
A More Honest Classifier
The classifier decides which group a prompt belongs to. In 1.5.4, its story was mostly „Ollama does the classification.“ Reality was messier, and v1.6.0 makes the router tell the truth about it.
There’s now a robust cloud fallback chain for the classifier (opt-in via classifier_cloud_fallback): pinned model → probe-verified list → tiered discovery → configured free models → static classification. And crucially, it runs before Ollama.
Why before Ollama, when local models are free? Because on my M3 Pro, local classification turned out to be a resource problem more than a cost win. While an Ollama model loads and churns through a classification, the session it’s supposed to route is already waiting. Either it gives up and starts with some other model, or the extra memory pressure pushes the whole machine to the edge of collapse. Classification has to be fast, and it must never compete with the real work for resources; a small cloud model from OpenRouter or Mistral does that without touching the Mac at all. Local classification stays in the game as the last resort, supervised by the daemon watchdog I’ll get to in a bit.
The scan now performs a quality probe instead of just checking reachability. I had a model that was perfectly reachable, and it dutifully answered every classification prompt with chatty narration instead of an actual verdict. The probe runs three real classification cases and caches the verdict, so models that talk but don’t deliver get filtered out before they ever reach the fallback chain.
Router narration is now stripped from all classifier inputs. The 1.5.4 fix was incomplete, and two paths had still been passing raw narration through. Exclude rules also apply universally now, including to pinned classifier models: „never use“ means never, a decision I made on October 3rd after a review showed one quietly ignoring the exclusion.
And /router status no longer lies. It shows which backend actually delivered the last classification (cloud model, cache, or static fallback), plus the executed chain and live status.
Failure Handling: The Router That Learns
Next, the error department. This is where „dynamic“ gains a second meaning: not just switching models, but adapting to what actually happens at runtime. Highlights:
- A learned model blocklist. The router observes permanent failure signatures and auto-blocks models that keep failing; repeated unknown errors promote a model onto the blocklist after a streak. On top of that, a static blocklist for free models that are permanently guardrail-blocked.
- Patience with short rate limits. Instead of burning through the whole candidate chain when a provider says „try again in 30 seconds“, the router waits out short resets.
- Calmer escalation. Bare 422/403 responses no longer trigger hard cooldowns. The tool-result rate-limit heuristic is gone entirely, because tool output is never evidence of this model’s limits. Answers that merely mention limits no longer get killed mid-stream, and
stopReason: 'length'is caught as a soft failure instead of a mystery. - A watchdog for the local daemon. The Ollama daemon can wedge (an MLX runner bug in 0.33.3), and the router now probes it and skips
ollama/*candidates when it’s down, instead of letting every stream die against a dead daemon.
Registry Discipline: The Router Registers (Almost) Nothing
This is the change I’d highlight to anyone building something similar, because it’s a root-cause fix of a whole bug family.
Until now, the router registered scan-discovered models in Pi’s registry. As of this release, it doesn’t. Pi’s registry is the single source of truth for cloud inventory, and the scan only enriches it. The old behavior caused a plague of Mistral 422 „store“ errors: 29 invented Mistral registrations, OCR and audio models registered as chat models. The remaining registrations are deliberate: local Ollama models, explicitly configured free_models, and virtual groups.
And speaking of Ollama registrations: they’re now a merge instead of a wipe. A guard used to compare tagged scan IDs against untagged registry IDs and wiped user registrations 83 times in a row. Now pi-known models round-trip with their typed fields, dedup happens on normalized IDs, the real contextWindow comes from /api/show, and user provider options survive.
Under the Hood
None of this would have been maintainable without some cleanup, and I’m proud of this one: index.ts went from roughly 3750 lines down to about 640, via twelve extractions into createX(deps) factory modules. The factories receive live getters instead of closure captures, which kills the entire „stale config captured at startup“ bug class. Pure code motion. The suite stayed green at every step.
A few more worth mentioning:
| Area | What changed |
|---|---|
| Logging | A real level axis (error → warn → info → debug), ~24 previously unclassified call sites sorted, 20MB/4-rotation policy. Release builds now ship quiet (log_level: "warn"), enforced by a gate test, not by hope. |
| Observability | /router cost (per-model audit report from the router’s own token accounting), /router errors (session error log with status-line correlation), and a KPI audit script over router.log. |
| Packaging | No runtime state in the npm package (guarded), config writes persist only deltas, a shared whitelist drives both staleness resyncs, and SIGTERM/SIGINT persist best-effort before exit. |
| Guardrails | A static test forbids any setModel() call in production code outside the user tool. The legacy hook that caused subtle routing bugs is gone for good. |
| Docs | 21 ADRs, all docs translated to English, one changelog instead of two overlapping ones. |
By the Numbers
| Metric | v1.5.4 | v1.6.0 |
|---|---|---|
| Test files | ~93 | 139 |
| Tests | ~930 | 1140 passing / 3 skipped |
| index.ts | ~3750 lines | ~640 lines |
| Modules (src/) | ~30 | ~45 |
| Free-traffic share | not tracked | 61.5% (current project) |
That last row is the one I care about most: after the billing, cost-resolution, and delegation work, 61.5% of the traffic in my current project runs on free models, with no noticeable quality drop in day-to-day work.
Wrapping Up
If you’ve been following along since the Smart Model Routing post: this release is where the router stopped being a clever sorter and started being an operator. It knows what things cost, it admits what it did, and it remembers what broke.
As always, the router is available as an open-source project on GitHub: github.com/ANierbeck/pi-model-dynamic-router, and installable via Pi: @anierbeck/pi-model-dynamic-router.
Disclaimer: This blog post was written by me, with the help of Vibe (formerly known as Le Chat), an AI assistant by Mistral AI.
Schreibe einen Kommentar